Higher education
Secure internal AI assistant for staff
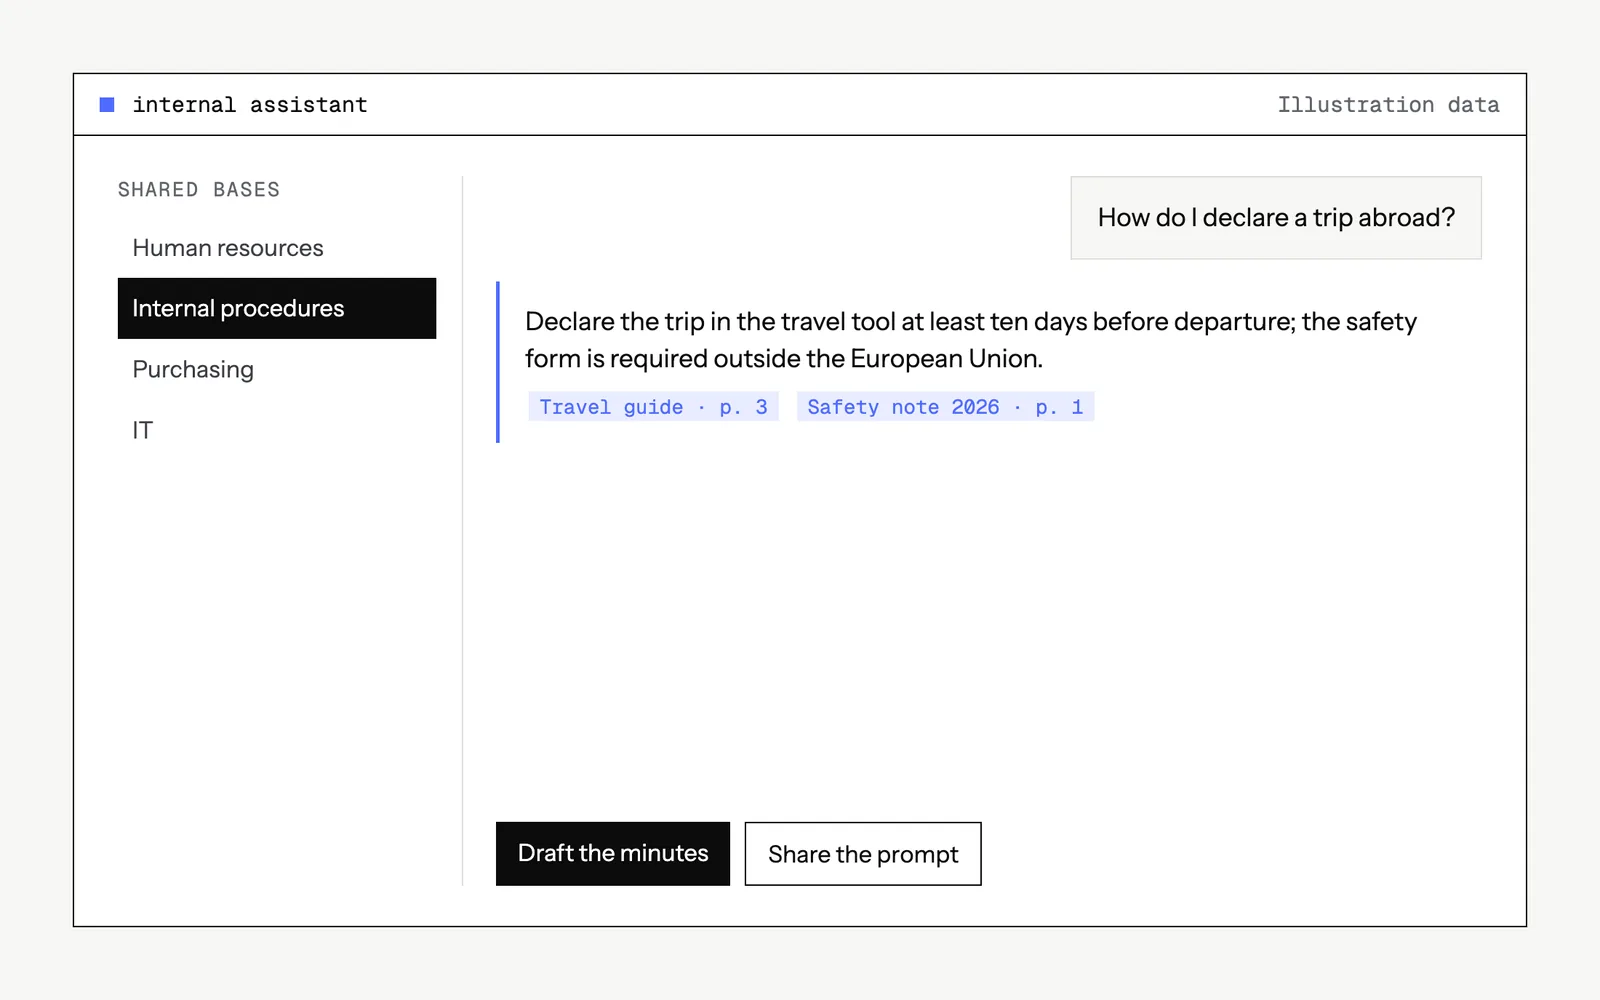
Staff at a large multi-site group query internal knowledge in a controlled environment, with sourced answers. The organisation keeps its content within a closed loop and chooses the right model for each use.
Context
A large multi-site group running around 140 applications, which wanted a shared AI tool without letting its internal content leak into consumer tools.
The problem
Scattered AI usage, internal content copied into external tools, and internal information that was hard to find and sometimes out of date.
What we built
A multilingual conversational assistant connected to the knowledge base: document search with sources displayed, shared knowledge bases with group-based permissions, shared prompts, a personal document base, meeting minutes, and user feedback on every answer so that the source content can be corrected. Access to several models through a single gateway.
Steps
- 01Shared back-end (FastAPI, hexagonal architecture) and front-end foundation, enterprise authentication
- 02Ingestion and search pipeline: chunking, embeddings, reranking, citations
- 03Specialised agents (global search, per-base search, web) and multi-model gateway
- 04Go-live on the client's cloud, with separate staging and production environments
Hosting and models
Client's Azure cloud (West Europe): API and workers in managed containers, PostgreSQL with vector search, object storage. Open embedding and reranking models (Qwen3 family) served by vLLM on dedicated GPU machines. Commercial large models (Gemini, Claude) called via a LiteLLM proxy, which avoids dependence on a single provider.
Services involved
Agentic platforms · AI in your applications · Forward Deployed Engineers
We name a client only with their written agreement. The budgets and detailed results of our engagements remain confidential.