Energy · Industry
Document search assistant with cited sources
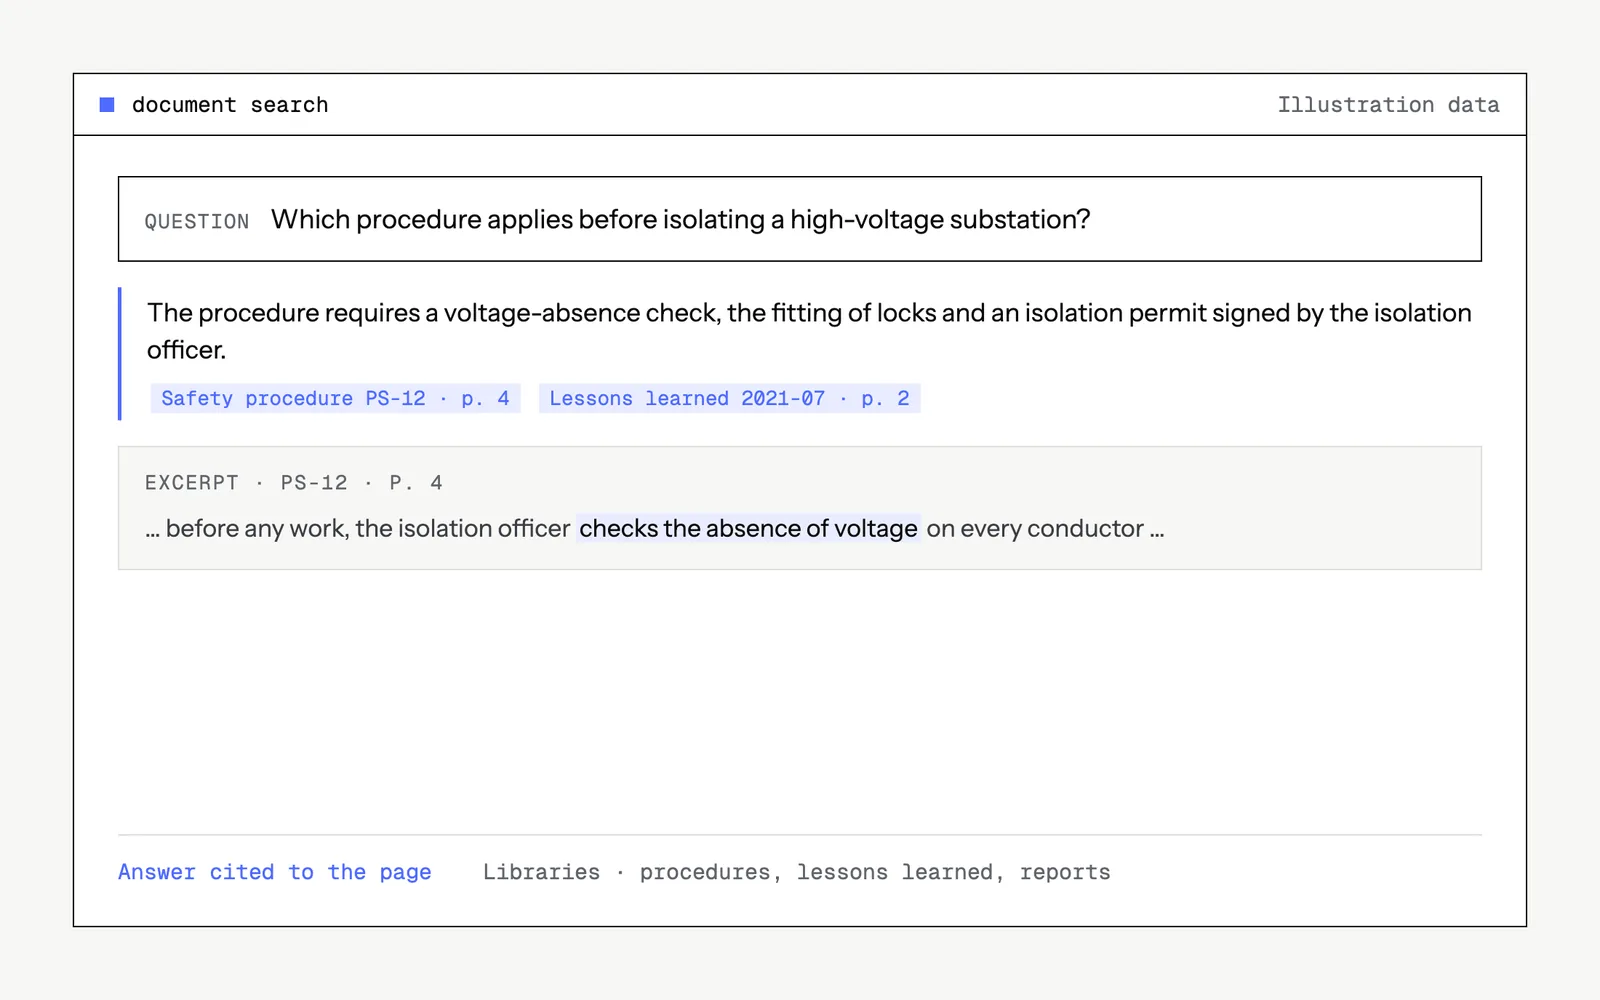
Teams query their technical documents, procedures and lessons-learned reports in natural language, and every answer points back to the document and page it came from.
Context
A large energy group has accumulated technical documents, lessons-learned reports and project files for years, stored in libraries that are not easy to query.
The problem
Finding a piece of information buried in thousands of documents, some running to several hundred pages and in several languages, took hours, and generic tools did not cite their sources.
What we built
An internal conversational platform: document ingestion (OCR, extraction, chunking, vectorisation), hybrid search with reranking, answers that cite the source page, personal workspaces and shared knowledge bases, web search, user memory, and authentication through the company directory. The platform is now being rebuilt on a more robust architecture, without changing what it does for users.
Steps
- 01Ingestion and indexing of the document libraries (OCR, chunking, vectorisation)
- 02Hybrid search, reranking and answers cited to the page
- 03Deployment on the client's private cloud, connection to the company directory
- 04Feedback collected from users and ongoing support
Hosting and models
OVHcloud private cloud in France (managed Kubernetes, PostgreSQL, S3 storage, Gravelines data centre). Main model Qwen3.5-397B served by OVHcloud AI Endpoints. The gateway of the production version also declares Claude models via AWS Bedrock (EU and US regions).
Services involved
Agentic platforms · Forward Deployed Engineers · Training & maintenance · AI & Cloud Strategy
We name a client only with their written agreement. The budgets and detailed results of our engagements remain confidential.